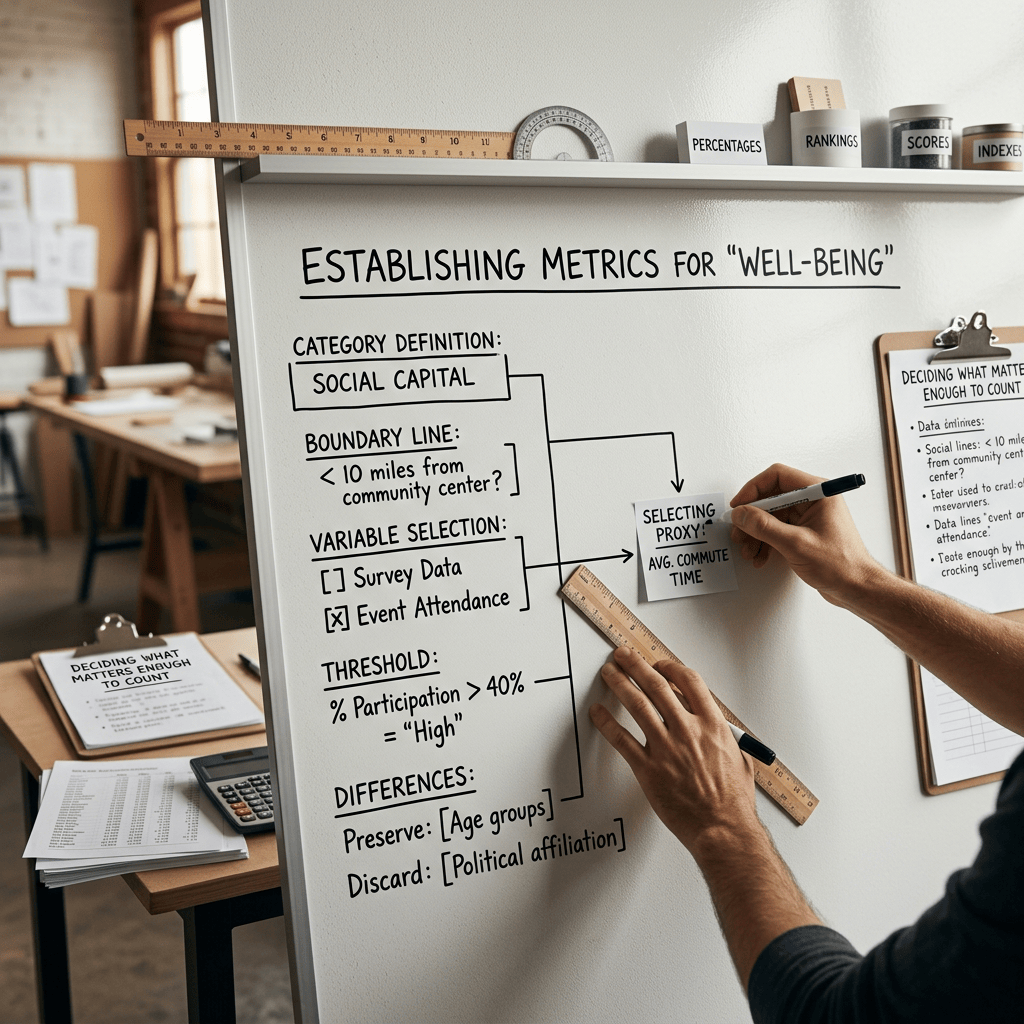
Measurement appears neutral because it speaks in numbers.
A percentage seems objective. A ranking appears comparable. An index looks systematic. A score suggests precision. Once a social condition is translated into a metric, disagreement appears to become easier to manage because numbers seem to stand outside interpretation.
Yet measurement is never only about counting.
Before anything can be measured, someone must decide what matters enough to count. A category must be defined. A boundary must be drawn. A variable must be selected. A threshold must be established. Some differences will be preserved, while others will be treated as insignificant.
These choices are not merely technical.
They shape how institutions see the world.
Measurement therefore has a political dimension, not because every number is manipulated, but because every system of measurement reflects decisions about relevance, visibility, and value.
The politics begins before the calculation.
Deciding What Counts
Institutions cannot measure everything.
They must select.
A government may measure unemployment, income, school participation, health outcomes, crime, land ownership, service delivery, infrastructure, or public satisfaction. An organization may monitor productivity, efficiency, attendance, customer experience, financial performance, or risk.
Each choice creates attention.
Once something is measured regularly, it gains institutional presence. It appears in reports, meetings, dashboards, evaluations, and strategic discussions. It becomes easier to discuss because it has a number attached to it.
Other realities may remain less visible.
This means measurement is not only descriptive. It is also selective.
To measure one thing is often to give it institutional priority over something else.
The issue is not that institutions make these choices. They have no alternative. The issue is whether those choices remain visible and open to scrutiny.
An indicator can appear natural after it has been used long enough.
Its assumptions disappear.
The metric begins to feel inevitable.
Yet every indicator contains a history of selection.
Categories Create Reality
Measurement depends on categories.
Before a population can be counted, it must be classified.
Before performance can be compared, performance must be defined.
Before risk can be scored, risk must be translated into observable variables.
Categories make complexity manageable, but they also impose structure on reality.
Geoffrey Bowker and Susan Leigh Star showed how classification systems are deeply embedded in social organization. Categories are not merely administrative conveniences. They shape what becomes visible, what becomes comparable, and how institutions act.
This becomes especially important when categories affect people directly.
A person may be classified as eligible or ineligible.
A neighborhood may be classified as high risk.
A school may be classified as low performing.
A region may be classified as underdeveloped.
Once created, these categories can influence resources, attention, and policy.
Classification therefore does not simply describe difference.
It can institutionalize difference.
The political significance lies in the fact that categories often appear technical after they have been formalized.
The debate shifts from whether the category is appropriate to whether the data has been entered correctly.
The original judgment disappears behind administrative routine.
The Authority of Indicators
Indicators gain power because they travel easily.
A complex situation may require hundreds of pages to explain.
An indicator reduces that complexity to a number.
This makes it portable.
A minister can compare regions. A manager can compare units. An international organization can compare countries. A donor can compare programs. A board can compare performance across years.
The simplification is useful.
It is also consequential.
Sally Engle Merry argued that indicators transform complex social phenomena into simplified numerical forms that can circulate across institutions. In doing so, they make comparison possible while also stripping away some of the context from which the original conditions emerged.
This creates a tension between visibility and reduction.
The indicator makes something easier to see.
At the same time, it may make the underlying reality harder to understand.
A low score can identify a problem.
It cannot always explain why the problem exists.
A high score can demonstrate improvement.
It cannot always reveal who benefited from that improvement.
Indicators therefore acquire authority because they provide clarity.
But clarity can sometimes conceal complexity.
Measurement and Power
Measurement becomes political when it influences consequences.
A number becomes especially powerful when it is connected to funding, promotion, sanctions, reputation, eligibility, or institutional legitimacy.
At this point, measurement no longer merely observes behavior.
It begins to shape it.
Organizations adapt to what is measured.
Managers respond to targets.
Employees learn which indicators matter.
Institutions reorganize attention around performance systems.
This is understandable.
Measurement creates incentives.
But incentives can transform the object being measured.
A school judged primarily by test results may focus increasingly on test performance. A hospital evaluated through specific outcomes may concentrate resources on those indicators. A public agency assessed through completion rates may reorganize work around what can be completed most visibly.
The metric begins to participate in creating the behavior it was designed to evaluate.
This is why measurement systems should never be treated as passive.
They intervene.
They reward some activities and weaken attention to others.
They create institutional signals about what matters.
Measurement becomes governance.
The Problem of Comparability
Comparison is one of the strongest attractions of measurement.
Numbers allow institutions to place different entities within a common frame.
Cities can be ranked.
Countries can be compared.
Schools can be scored.
Public agencies can be assessed against common targets.
This creates a sense of fairness because everyone appears to be judged by the same standard.
But comparison requires commensuration.
Different realities must be transformed into a common metric.
Wendy Espeland and Mitchell Stevens describe commensuration as the process of reducing different qualities into a common scale. This process creates powerful forms of comparability, but it also requires certain differences to be ignored.
Two institutions may receive the same score despite operating under very different conditions.
Two regions may appear unequal because the metric does not capture local constraints.
Two individuals may be compared through standardized categories that do not reflect their circumstances.
Comparison is therefore never purely descriptive.
It is constructed.
The question is not whether comparison should be abandoned.
It is whether institutions remain aware

